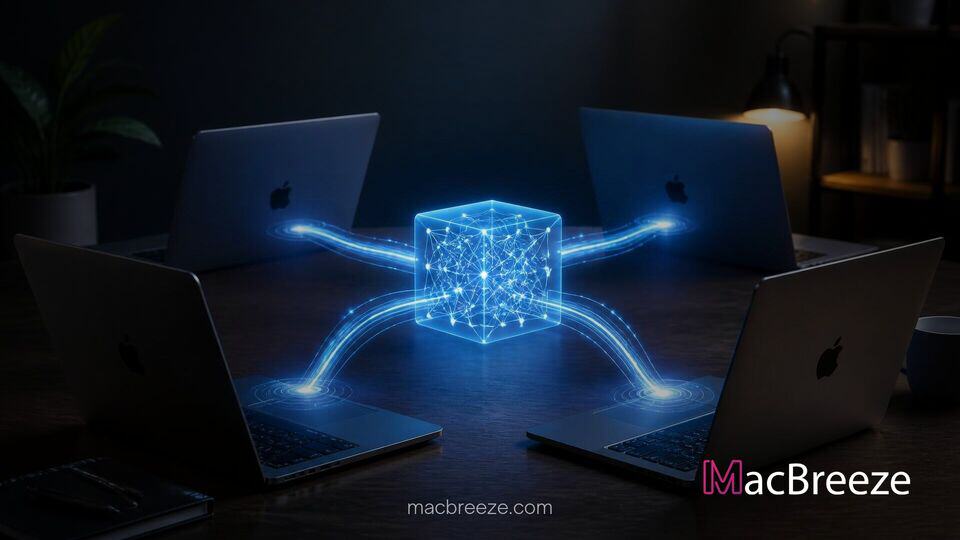
The open-source development team behind oMLX has officially released version 0.7.4, introducing a feature that allows multiple Apple Silicon Macs to pool compute power for local large language model inference. Designed specifically to solve prompt processing bottlenecks when running large models, the update enables paired Mac setups to achieve up to 2.9 times faster prefill speeds.
By offloading initial context evaluation to a secondary machine with a faster graphics processor, developers and AI enthusiasts can process multi-thousand-token prompts in a fraction of the time. This release marks a significant milestone in local artificial intelligence execution, turning separate desktop and laptop setups into coordinated compute clusters without relying on cloud infrastructure.
OMLX Mac Distributed Local LLM Prefill: How the New Architecture Accelerates Workloads
In large language model workflows, inference is split into two distinct stages: prompt evaluation (prefill) and token generation (decoding). The prefill phase requires evaluating the entire context window at once, which demands massive compute bandwidth, especially when processing code repositories, long documents, or deep conversational histories. While high-memory systems like Mac Studio can store large parameter sets, their compute throughput during prefill can become a major operational bottleneck.
The oMLX v0.7.4 update addresses this limitation through a dedicated feature known as the Prefill Accelerator. Under this architecture, a primary Mac with high unified memory capacity maintains ownership of the full model, retains the Key-Value (KV) cache, and manages token generation. Meanwhile, a secondary Mac with a higher-performance GPU processes the early transformer layers of incoming prompt chunks.
Because the prefill task is parallelized across both machines over a local network, prompt processing latency drops dramatically. Initial developer benchmarks demonstrate that pairing an M3 Ultra machine (512GB RAM) with an M5 Max machine (128GB RAM) yields a 195 percent speedup when evaluating 64,000-token prompts on DeepSeek V4.1 Flash, jumping from 1,060 to 3,123 tokens per second. Similar gains were observed on other open models, including Qwen3.8 Flash-Next (+180%), GLM-5.3 Flash (+157%), and MiniMax M3.1 (+92%).
Hardware and Local Network Requirements for macOS Users
Setting up distributed prefill in oMLX v0.7.4 does not require specialized enterprise networking hardware or Remote Direct Memory Access (RDMA) configurations. The system relies on standard high-bandwidth local connections, such as Thunderbolt networking or 5GbE connections, though standard 2.5GbE links also provide substantial speedups. Developer guidance indicates that keeping network latency under 10 milliseconds is optimal for preventing communication overhead from eroding performance gains.
Both machines in the cluster must run compatible versions of macOS and have oMLX v0.7.4 installed. Users enable the distributed mode in global application settings on both devices, pair the hardware within the built-in Cluster tab, and select the designated helper Mac within individual model profiles. The host machine continues to handle decoding independently, meaning token output generation speeds remain bounded by the primary machine's memory bandwidth.
This distributed setup complements ongoing software advancements across Apple Silicon hardware. As research projects like Apple's Minions virtual GPU cloud architecture explore pooling idle Mac resources, open-source tools such as oMLX are actively putting consumer-facing multi-device execution into practice today.
Benchmark Performance and Developer Productivity Gains
For developer workflows centered around local coding assistants, agentic tool invocation, and automated document analysis, prefill speed is the primary driver of response latency. Traditional local inference servers recompute prompt histories on every request turn, often causing long wait times when context windows exceed 30,000 tokens.
In addition to multi-Mac distributed prefill, oMLX v0.7.4 incorporates single-machine optimizations that boost Metal kernel performance. By implementing a bounded buffer pool throughout the neural network layer loops, single-node prefill speeds increased by 43 to 48 percent on M5 Ultra chips when testing DeepSeek V4.1 models. Furthermore, fresh shader compilation delays have been reduced, and activation prefill pipelines have been updated to support mixed-precision quantizations.
These speed increases directly benefit tools built on top of local APIs. As developers adopt privacy-centric applications like Local Code for macOS, minimizing time-to-first-token (TTFT) keeps local artificial intelligence assistants feeling responsive and competitive with cloud-hosted commercial endpoints.
The Growing Ecosystem for On-Device Mac AI Computing
The release of oMLX v0.7.4 reflects a broader movement across the software ecosystem to unlock the full potential of Apple Silicon's unified memory architecture. By eliminating memory copying overhead between isolated system memory and dedicated VRAM, Apple chips provide an advantageous hardware base for local inference.
Industry collaboration has continued to push local boundaries further. Recent joint projects have demonstrated high-parameter model optimization on Apple hardware, such as when Meta and Apple optimized the Muse Spark Open model for Mac Studio setups. Concurrently, corporate leadership has emphasized hardware-level focus on machine learning tasks, highlighted when Apple executives outlined their on-device AI strategy prioritizing privacy and local hardware execution.
While system resources remain a consideration, as shown by reports that Apple Intelligence storage footprints can exceed 30GB, open-source server tools give power users fine-grained control over model caching, precision tiers, and distributed compute scaling.
Concluding Remarks
By bringing distributed prefill functionality to local macOS clusters, oMLX v0.7.4 eliminates one of the biggest friction points in running large open-source language models on personal hardware. By allowing users to combine the high RAM capacity of an older workstation with the raw graphics compute of a newer laptop or desktop, the project demonstrates a scalable path forward for self-hosted AI compute. The v0.7.4 release is currently available for download via GitHub and standard macOS package managers.